· 10 min read · Nadeera Silva
pgvector 0.8.7 Security Fix: Upgrade, Then Pick HNSW or IVFFlat
pgvector 0.8.7 fixes a high-severity IVFFlat bug. Check your version, upgrade on Docker or Supabase, and choose between HNSW and IVFFlat.
If you run pgvector for search or RAG, check its version this week. pgvector 0.8.7, released on 1 October 2026, fixes CVE-2026-103484, a buffer overflow in IVFFlat index builds that can lead to arbitrary code execution on the database server. Every version before 0.8.7 is affected. This post shows how to check which pgvector version each database is running, how to upgrade on self-hosted Postgres, Docker and Supabase, and then answers the question most people search for next: should you use HNSW or IVFFlat?
What the pgvector 0.8.7 security fix covers
The GitHub advisory issue #1036 says a database user who can create an IVFFlat index can write data out of bounds, which can lead to arbitrary code execution. Versions 0.8.6 and below are affected, and 0.8.7 is the fix. The CVE record scores it 8.8 (High) under CVSS 3.1, with network access and low privileges required. It was reported by researchers at Compass Security.
In plain terms: the attacker needs a database login that is allowed to build an IVFFlat index. That rules out anonymous visitors to your app, but it does not rule out a compromised service account, a shared database where several teams or tenants can run DDL, or an internal tool that lets users create their own tables. Red Hat's assessment notes that code would run with the privileges of the Postgres service account, and that setups where untrusted clients cannot create database objects are not exposed.
It is also not the first fix of this kind in 2026. The CHANGELOG shows a run of patch releases:
| Version | Date | Fix worth knowing about |
|---|---|---|
| 0.8.2 | 2026-02-25 | Buffer overflow in parallel HNSW index builds (CVE-2026-3172, affected 0.6.0 to 0.8.1) |
| 0.8.3 | 2026-06-17 | Possible index corruption with HNSW vacuuming |
| 0.8.4 | 2026-06-30 | hnsw graph not repaired error during HNSW vacuuming |
| 0.8.6 | 2026-07-29 | IVFFlat buffer overflow on 32-bit systems (CVE-2026-18022) |
| 0.8.7 | 2026-10-01 | IVFFlat buffer overflow on all platforms (CVE-2026-103484) |
So if you are still on 0.8.0 or 0.8.1, the upgrade covers more than one security issue, including the HNSW one in issue #959, which could leak data from other relations or crash the server.
How to check your pgvector version
pgvector is installed per database, and the extension name in SQL is vector, not pgvector. Run this in every database that uses it:
SELECT extversion FROM pg_extension WHERE extname = 'vector';That tells you what the database is using. To see whether the server already has newer files installed, compare it with the default version:
SELECT name, default_version, installed_version
FROM pg_available_extensions
WHERE name = 'vector';
If default_version is 0.8.7 and installed_version is lower, the new build is on the server and you only need the ALTER EXTENSION step below. If both show an older version, the server itself needs the new package or image first.
To find out whether you even have IVFFlat indexes, list your vector indexes by access method:
SELECT schemaname, tablename, indexname, indexdef
FROM pg_indexes
WHERE indexdef ILIKE '%USING ivfflat%' OR indexdef ILIKE '%USING hnsw%';
How to upgrade pgvector
The README's upgrade section is short: install the latest version using the same method you used originally, then update the extension in each database.
ALTER EXTENSION vector UPDATE;
SELECT extversion FROM pg_extension WHERE extname = 'vector';  -- expect 0.8.7
The repository ships an update script for each step (for example vector--0.8.6--0.8.7.sql), so Postgres can walk from an older 0.8.x version to 0.8.7 in one command. Postgres loads an extension's shared library into each backend process when it is first used, so after replacing the files I restart Postgres or recycle pooled connections to make sure nothing keeps running the old build.
Self-hosted Postgres (APT, Yum, source)
Use the same package source as before. On Debian or Ubuntu with the PostgreSQL APT repository, the package is postgresql-18-pgvector (swap 18 for your major version), and the 0.8.7 package reached apt.postgresql.org on 5 October 2026. On RPM systems it is pgvector_18. From source:
cd /tmp
git clone --branch v0.8.7 https://github.com/pgvector/pgvector.git
cd pgvector
make
sudo make install
pgvector in Docker
The official pgvector/pgvector image adds the extension to the standard Postgres image. Moving tags such as pg18 or pg18-trixie now point to 0.8.7, and there are pinned tags such as 0.8.7-pg18-trixie. I prefer the pinned tag in docker-compose.yml, so an upgrade is a visible change in a pull request:
services:
  db:
    image: pgvector/pgvector:0.8.7-pg18-trixie
    shm_size: 1g
    environment:
      POSTGRES_PASSWORD: ${POSTGRES_PASSWORD}
    volumes:
      - pgdata:/var/lib/postgresql  # 18+ images; 17 and older mount /var/lib/postgresql/data
volumes:
  pgdata:
Pull the new image, recreate the container on the same volume, then run ALTER EXTENSION vector UPDATE; in each database. Keep the Postgres major version in the tag the same as the one your volume was created with, and note that from Postgres 18 the base image expects the volume at /var/lib/postgresql instead of /var/lib/postgresql/data. The shm_size line matters if you raise maintenance_work_mem: the README says shared memory must be at least that size to avoid errors with parallel HNSW builds.
Supabase pgvector
On Supabase you do not install packages yourself. The extensions docs say a newer extension version only becomes available after a software upgrade, which you start in the project's General Settings (restarting the server there also triggers it). After that, run the bare update in the SQL editor:
alter extension vector update;
select extversion from pg_extension where extname = 'vector';Amazon RDS and other managed Postgres
Managed providers decide which pgvector versions you can install. AWS's extension versions page says it plans to offer new extension versions in the next quarterly release, and that extensions do not upgrade automatically when you upgrade the engine. Run the pg_available_extensions query above after each minor version upgrade, and apply the index privilege restrictions while you wait.
Do I need to rebuild my indexes?
The 0.8.7 advisory does not ask you to rebuild existing indexes; the bug is in the build path. Older releases did say so when it mattered (0.3.1 asked users to recreate IVFFlat indexes), so read the notes for every version you skip. If an untrusted user could build IVFFlat indexes on a vulnerable version, treat it as a possible compromise of the database host, not just a patch job.
HNSW vs IVFFlat in 2026
Once you are patched, the index question is still there. Both index types give approximate nearest neighbour search, which means you trade some recall for speed, and results can change compared with an exact scan. Here is how the pgvector README compares them:
| HNSW | IVFFlat | |
|---|---|---|
| Structure | Multilayer graph | Vectors split into lists (k-means) |
| Speed vs recall | Better | Lower |
| Build time and memory | Slower, more memory | Faster, less memory |
| Can build on an empty table | Yes, no training step | No, build after loading data |
| Build options | m (16), ef_construction (64) | lists |
| Query option | hnsw.ef_search (40) | ivfflat.probes (1) |
Max indexed vector dimensions | 2,000 | 2,000 |
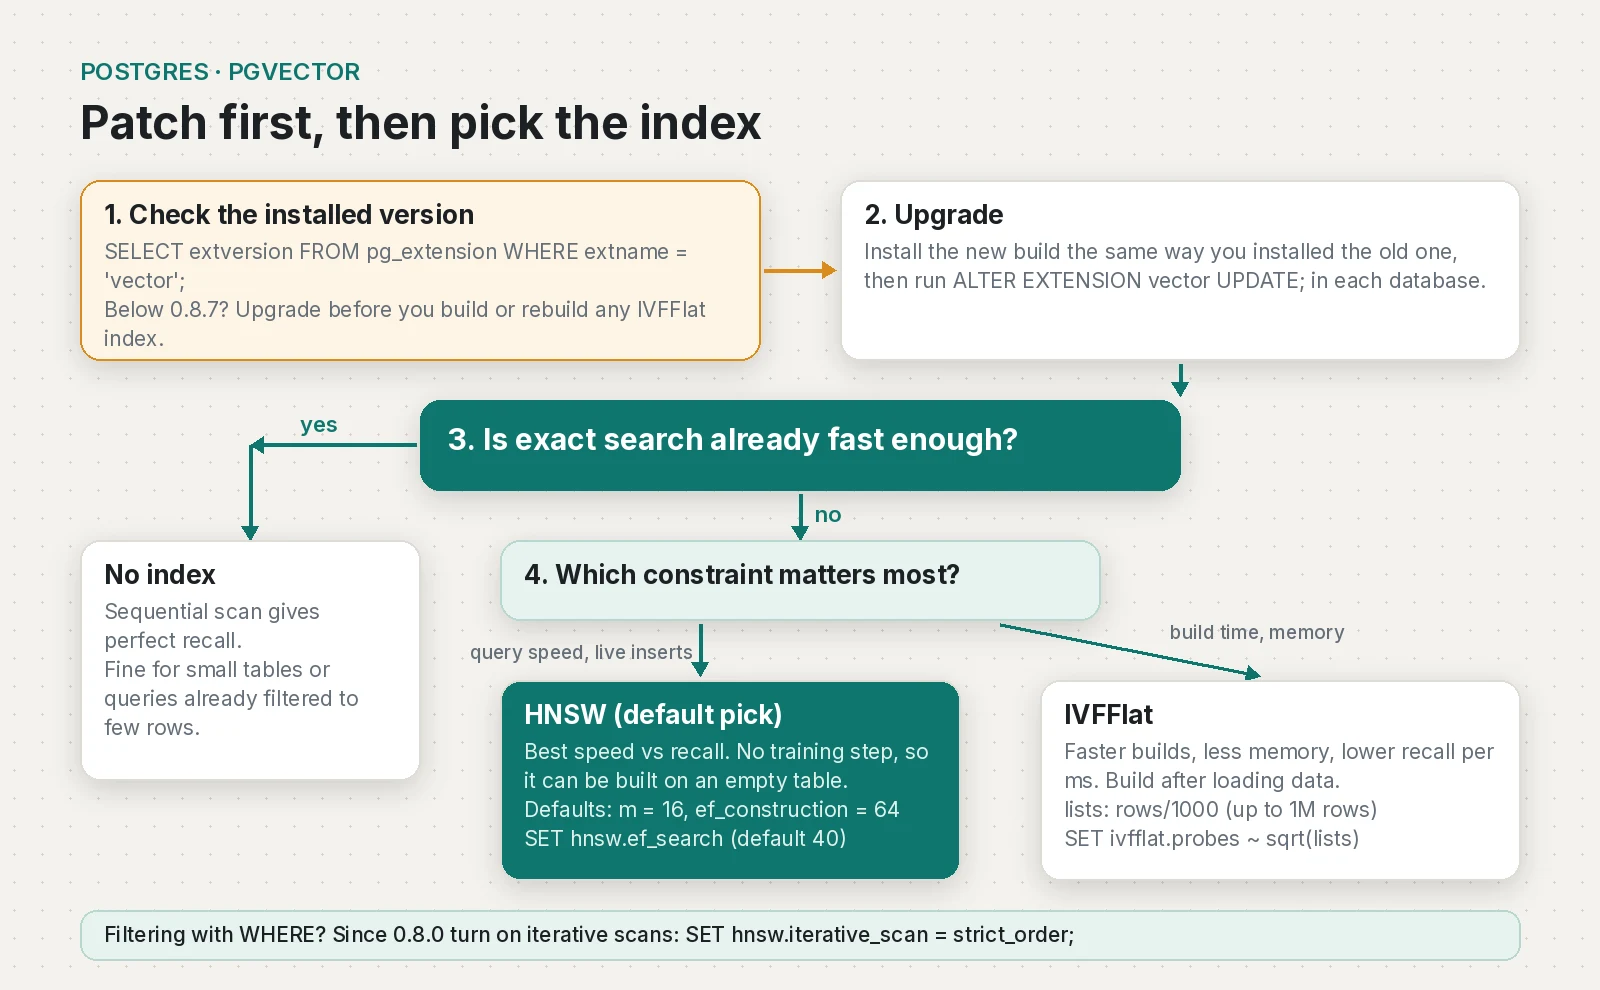
My default for a RAG app is HNSW. Documents arrive over time, queries need to be fast, and there is no training step to redo as the data grows. IVFFlat makes sense when you load a large, mostly static dataset in one go and build time or memory is the real constraint. And for a small table, or queries that already filter down to a few hundred rows, no vector index at all is a valid choice: a sequential scan gives perfect recall.
Creating a pgvector HNSW index
Use the operator class that matches the distance you query with. For cosine distance (<=>), which most embedding models use:
SET maintenance_work_mem = '2GB';
SET max_parallel_maintenance_workers = 3;

CREATE INDEX CONCURRENTLY chunks_embedding_hnsw
ON chunks USING hnsw (embedding vector_cosine_ops)
WITH (m = 16, ef_construction = 64);
CONCURRENTLY avoids blocking writes in production. The values shown are the defaults; the README suggests keeping them unless you see low recall. At query time, raise ef_search for a single transaction if recall is too low:
BEGIN;
SET LOCAL hnsw.ef_search = 100;
SELECT id, content
FROM chunks
ORDER BY embedding <=> $1
LIMIT 8;
COMMIT;
Creating an IVFFlat index
The README's starting point for lists is rows / 1000 up to 1M rows and sqrt(rows) above that, with probes around sqrt(lists). For a 200,000 row table that gives 200 lists and about 14 probes:
CREATE INDEX CONCURRENTLY chunks_embedding_ivfflat
ON chunks USING ivfflat (embedding vector_cosine_ops)
WITH (lists = 200);

SET ivfflat.probes = 14;
Build it after the data is loaded. An IVFFlat index created on a nearly empty table is a common reason for missing results, and the fix is to drop it and build it again later.
Filtered queries and iterative scans
With either index, a WHERE clause is applied after the index scan. The README's example: with HNSW, the default ef_search of 40 and a filter that matches 10% of rows, you get about 4 results on average. Since 0.8.0 you can turn on iterative scans so pgvector keeps scanning until it has enough rows:
SET hnsw.iterative_scan = strict_order;
-- or, for IVFFlat
SET ivfflat.iterative_scan = relaxed_order;
For multi-tenant data, the README recommends list partitioning or separate tables, because a shared index lets one tenant's vectors affect another's recall. I covered the tenant filter and citations side of this in RAG with citations on PostgreSQL and pgvector.
pgvector vs a dedicated vector database
Search interest in Qdrant has risen alongside pgvector this year, and it is a fair question. My rule is simple: if your embeddings sit next to relational data you already filter and join on, pgvector keeps it all in one transaction, one backup and one permission model. The trade-off, as this release shows, is that the extension runs inside your database process, so its patches are your database's patches. If vector search is a separate, very large workload, a dedicated engine can be worth the extra system. The RAG post has a longer comparison.
A note on PostgreSQL 19
PostgreSQL 19 RC 1 came out on 15 October 2026, with general availability planned for 19 November 2026. A major version upgrade uses pg_upgrade or dump and restore, and the new cluster needs pgvector installed before you start. Also note that the CHANGELOG lists the unreleased 0.9.0 as dropping support for Postgres 13 and 14, so very old clusters should plan both upgrades together.
pgvector upgrade checklist
- Run the
extversionquery in every database that has thevectorextension. - Compare
installed_versionwithdefault_versionto see if the server already has 0.8.7. - Restrict index creation to your migration role until the upgrade is done.
- Upgrade the package, Docker tag or Supabase software version, then run
ALTER EXTENSION vector UPDATE;in each database. - Restart Postgres or recycle pooled connections.
- Remove version pins from migrations, especially on Supabase.
- Review your indexes: HNSW by default, IVFFlat for large static loads, and iterative scans for filtered queries.
- Add the version query to your deploy checks so the next patch is not a surprise. My CI/CD pipeline post shows where a check like this fits.
Frequently asked questions
How do I check which pgvector version I have?
Run SELECT extversion FROM pg_extension WHERE extname = 'vector'; in each database that uses it. The extension is called vector in SQL, and each database can be on a different version.
Which pgvector versions are affected by CVE-2026-103484?
All versions before 0.8.7. The bug is an out-of-bounds write during IVFFlat index builds, it needs a database user who can create an IVFFlat index, and it is rated 8.8 (High).
How do I upgrade pgvector on Supabase?
Start a software upgrade or restart from the project's General Settings so the new version is available, then run alter extension vector update; in the SQL editor. Supabase now ignores explicit version pins, so remove them from migrations.
Should I use HNSW or IVFFlat in pgvector?
HNSW is the better default for most apps because it gives a better speed and recall trade-off and can be built on an empty table. IVFFlat builds faster and uses less memory, so it suits large, mostly static datasets loaded in one go.
Do I need to rebuild pgvector indexes after upgrading to 0.8.7?
The 0.8.7 advisory does not ask for a rebuild, because the bug is in the index build path. Read the notes for every version you skip, since some older releases did require rebuilding.
How do I run pgvector in Docker?
Use the pgvector/pgvector image with a pinned tag such as 0.8.7-pg18-trixie, which adds the extension to the official Postgres image. Then run CREATE EXTENSION vector; in your database.
Sources
- pgvector 0.8.7 Released (PostgreSQL, 2026-10-05)
- Buffer overflow with IVFFlat index build (issue #1036) (pgvector on GitHub, 2026-10-01)
- CVE-2026-103484 (CVE Program, 2026-10-01)
- CVE-2026-103484 (Red Hat)
- pgvector CHANGELOG (pgvector on GitHub)
- pgvector README (pgvector on GitHub)
- Buffer overflow with parallel HNSW index build (issue #959) (pgvector on GitHub, 2026-02-25)
- pgvector/pgvector Docker image (Docker Hub)
- Change PGDATA in 18+ to /var/lib/postgresql/MAJOR/docker (docker-library on GitHub)
- Postgres Extensions Overview (Supabase Docs)
- Extension version pinning is deprecated in favor of default versions (Supabase)
- Extension versions for Amazon RDS for PostgreSQL (AWS Documentation)
- PostgreSQL 19 RC 1 Released! (PostgreSQL, 2026-10-15)
Keep reading
- RAG with Citations on PostgreSQL and pgvector: How I Built ItHow I built RAG with citations on PostgreSQL and pgvector for Pactroom: schema, project-scoped retrieval, citation prompts and the HNSW filtering trap.
- How to Verify a Supabase JWT in Fastify with JWKSVerify Supabase JWTs in a Fastify API with JWKS and jose, handle the legacy JWT secret, rotate keys safely, and secure Socket.IO connections too.
- GitHub Actions CI/CD for a Solo SaaS: Tests, SSH Deploy and Prisma MigrationsThe GitHub Actions pipeline I run for Pactroom: tests, build, SSH deploy to a VPS, prisma migrate deploy and a health check, with a workflow you can adapt.
Comments
Share a question or note about this article.
Loading comments…